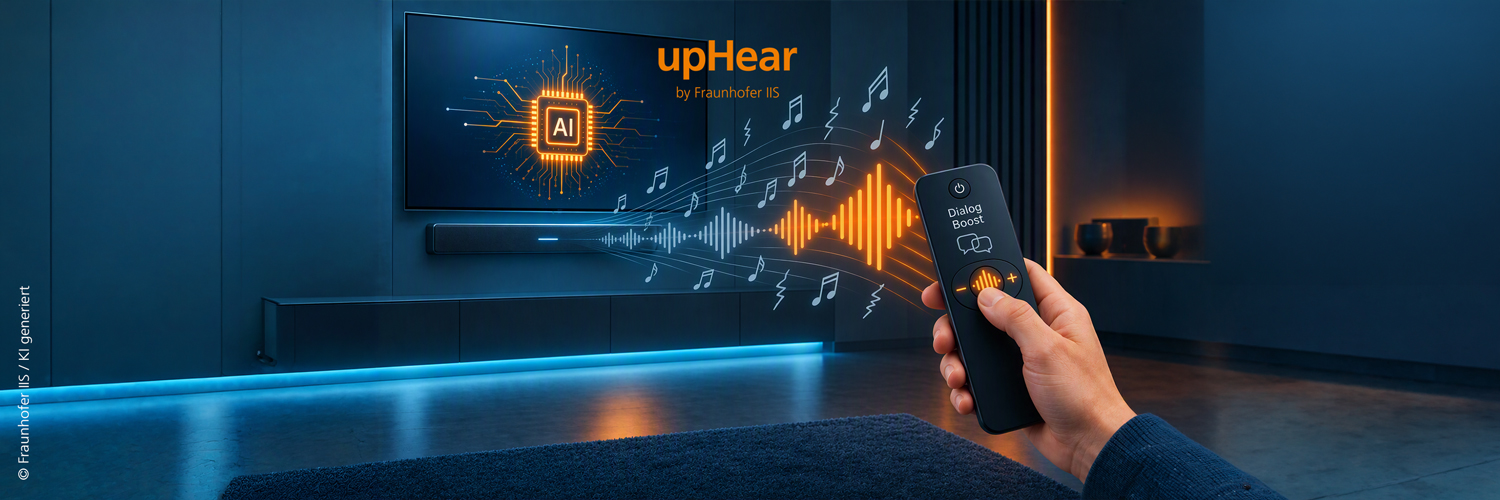
Fraunhofer IIS is expanding its upHear portfolio with a new technology designed to improve speech intelligibility in real‑time: upHear Live Dialog Boost. The module uses AI‑based dialogue separation to enhance spoken content for applications where latency is critical and footprint requirements are tight.
From Gain Control to AI‑Based Dialogue Isolation
Clear dialogue is one of the most frequently requested features in home entertainment. Many viewers report difficulty understanding speech in movies and TV shows – especially when background music or effects dominate the soundscape. Traditional audio processing can only go so far: simple gain adjustments also boost noise, and conventional DSP algorithms often introduce timbre coloration or distort the stereo image.
Fraunhofer IIS is well known for MPEG‑H Dialog+, a technology that has set a benchmark for dialogue enhancement in professional production and broadcast. upHear Live Dialog Boost builds on this long‑standing expertise and Dialog+ and upHear Live Dialog Boost share the goal of improving speech intelligibility. But both technologies serve distinctly different roles in the audio chain and take a different technical approach on dialogue enhancement.
upHear Live Dialog Boost combines dialogue enhancement with state‑of‑the‑art low-resource AI modeling: As opposed to legacy DSP approaches, it can semantically identify and isolate speech within complex audio scenes, preserving the original mix while improving clarity. upHear Live Dialog Boost brings this capability to embedded processors in consumer devices, enabling real‑time AI-based enhancement with minimum latency and memory requirements.
High‑Quality Results, Low Complexity
Key characteristics of upHear Live Dialog Boost include:
- Perceptually robust dialogue isolation, even in dense soundtracks
- Preservation of the original spatial audio image
- Low‑latency, real‑time processing for tight lip-sync requirements
- Lightweight AI models optimized for ultra-low memory footprint
- Modest compute requirements, suitable for general-purpose CPU’s without depending on proprietary neural processing architectures – especially at the mid-range and entry level.
upHear Live Dialog Boost integrates seamlessly into the existing upHear ecosystem and can be tailored to various hardware platforms as well as cloud and server‑based environments.
For embedded audio processing designs, the library is also available for established DSP integration platforms. This accelerates evaluation, implementation and tuning within existing signal flow design workflows.
Real‑Time Speech Enhancement at Device-Level
upHear Live Dialog Boost is a lightweight solution that scales across deployment contexts:
Applications are possible across endpoint playback devices, including TVs, set-top boxes, soundbars, streaming sticks, smart speakers and mobile devices. Besides audio devices, general deployment options include other real-time use cases for live applications and services where latency is critical.
The development of upHear Live Dialog Boost draws on knowledge spanning multiple research areas within Fraunhofer IIS – from audio system design and spatial processing to AI‑based speech enhancement and low‑complexity embedded implementations.
upHear Live Dialog Boost represents the core philosophy of the upHear portfolio of technologies: combining a high benchmark for perceptual quality with processing know-how at the edge-device level. Co-engineered by audio and AI DSP experts, upHear processing modules are built to empower device makers to create industry-leading audio products.